Every watt that enters an AI factory leaves it as heat. At conventional rack densities that is somebody else’s problem.
At the densities training clusters now run, two decisions follow from it: how the heat gets removed, and how much power the site has to draw at its worst moment.
Those questions usually sit with different people. They meet at the grid connection, now the scarcest thing in most European builds.
The European Commission’s AI Factories programme shows the scale: planned AI Gigafactories are expected to bring together more than 100,000 advanced processors per facility. A connection sized for that is not a formality.
Why training loads change the thermal problem
A training run holds thousands of GPUs at high utilisation for days or weeks, with processors, memory, networking and power components all producing heat at once and the load staying flat throughout.
That sustained concurrency separates AI factory cooling from a conventional enterprise estate, where load varies across the day and peaks are short.
When a device approaches its thermal limit it protects itself by slowing down. NVIDIA’s documentation calls this thermal throttling, with performance reduced once a defined temperature threshold is reached.
Distributed training makes the consequence much larger than the cause. In a tightly synchronised cluster every step waits for the slowest participant, so a thermal problem affecting a handful of nodes drags on the whole job.
The symptoms are longer and less predictable training times, and expensive accelerators returning less than they should.
The cooling options, in short
Most facilities run a combination. IEEE Spectrum groups the liquid approaches into four: single-phase and two-phase direct-to-chip, and single-phase and two-phase immersion.
- Air cooling – Chilled air moves through racks, with hot and cold aisle containment keeping exhaust away from intakes. Well understood and straightforward to maintain. As rack power climbs it needs more airflow and more fan energy, and the economics turn against it.
- Rear-door heat exchangers – A liquid-cooled door behind the rack takes exhaust air before it returns to the room. Adds capacity without bringing liquid inside the server, suiting retrofits and mixed-density halls.
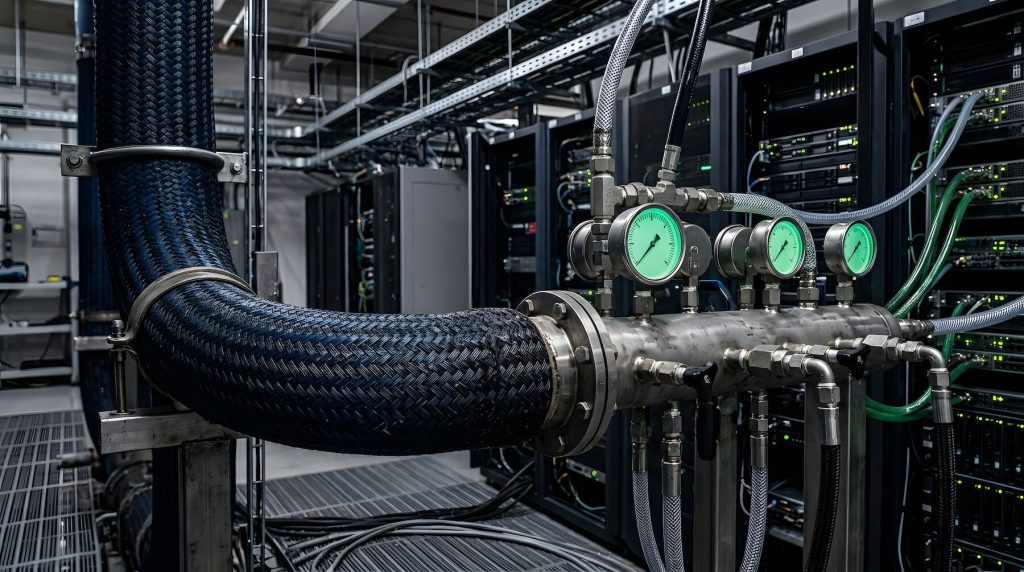
- Direct-to-chip – Coolant circulates through cold plates sitting on the hottest components. A coolant distribution unit moves that heat from the IT loop into the facility loop.
- Immersion – Whole servers sit in a non-conductive dielectric fluid, which either stays liquid or boils around hot components and condenses for reuse.
- Hybrid – Cold plates take the GPUs and CPUs while memory, power supplies, storage and networking still depend on airflow. This is where most current facilities land.
An industry overview describes the CDU as the main interface between the two loops, and why predominantly liquid-cooled clusters keep a separate air path for components not plumbed in.
What liquid cooling buys
Liquid carries heat better than air and captures it closer to the source. At current densities, that has stopped being a preference.
Richard Whitmore, who runs Schneider Electric’s Motivair cooling division, puts the threshold plainly in NVIDIA’s account: “Once the watts per chip crossed a certain level, liquid cooling became mandatory.”
The same source puts numbers against it. Cooling has historically accounted for up to 40% of a data centre’s electricity consumption, so efficiency here compounds quickly.
Raising chiller plant temperature by a single degree cuts cooling energy costs by roughly 4%, and NVIDIA estimates a 50 MW facility can save more than $4 million a year in cooling energy and water by moving to liquid.
The Rubin generation is designed for fully liquid-cooled operation, with coolant entering at up to 45°C and leaving at around 55°C, circulated as 75% water and 25% propylene glycol in a closed loop with no fans.
Running the loop that warm is the point. In many climates, the facility can reject heat through outdoor dry coolers without starting mechanical chillers, and water consumption falls from roughly 2.6 million gallons per megawatt per year towards zero.
Density improves too, with a system that previously occupied six rack units fitting into two.
NVIDIA is direct about the caveat. A site in the Scottish Highlands and one in Phoenix face different realities, and warmer coolant moves every site closer to chiller-free operation without delivering it everywhere.
Power flexibility is the other half
Thermal design settles how much compute a site can hold. What it draws from the grid, and when, is a separate question, and AI clusters turn out to be unusually good at flexing it.
National Grid reported a UK-first trial run with Emerald AI, EPRI, Nebius and NVIDIA on a cluster of 96 Blackwell Ultra GPUs at a London data centre:
- More than a third of electricity demand cut in under a minute, with high-priority workloads continuing to run.
- 30% of load shed within 30 seconds during a simulated system stress event.
- Load-reduction requests followed for up to 10 hours, covering extended periods of low wind or extreme heat.
- More than 200 simulated grid events sent to the site without warning across five days.
The mechanisms are ordinary enough. GPUs expose device-level power limits that can be lowered quickly, and schedulers can pause or defer lower-priority jobs.
Training work checkpoints cleanly, so it tolerates interruption in a way live inference serving does not. EPRI’s David Porter framed the significance in the same announcement: “The era of the ‘always-on’ AI factory is evolving.”
Where the two halves meet
A grid connection is sized on peak draw, and both decisions move that number. Liquid cooling lowers the overhead sitting on top of the IT load, because a facility rejecting heat through dry coolers for most of the year is not running a chiller plant alongside the racks. Power flexibility makes the IT load itself negotiable.
That is what National Grid was buying in the trial. A site able to reduce demand on request can be connected faster and at higher capacity, easing network charges over time.
For anyone planning European capacity, thermal design and workload flexibility belong in the connection application, not only the operations plan.
The reporting framework pushes in the same direction.
Commission Delegated Regulation (EU) 2024/1364 requires operators of data centres at or above 500 kW of installed IT power demand to report annually to the European database, and several indicators are specifically about cooling: temperature set points, power utilisation, water use and waste heat reuse.
The wider framework is set out in the post on the five-layer infrastructure model.
There is no single right cooling architecture. The questions that settle it are practical:
- Which servers support direct liquid or immersion cooling?
- Can the site reject heat without heavy dependence on water?
- Which workloads can be paused or power-capped, and which cannot?
- Can the facility collect the data the reporting framework asks for?
The AI-ready infrastructure pillar covers how those decisions sit against the rest of the stack.
Neurotechnology Cloud designs and operates AI factory environments on EU-resident capacity through its AI Infrastructure and AI Factory Engineering service, with thermal and power design handled alongside the compute specification.
If you are sizing a cluster against a fixed power envelope, get in touch.